
Pre-Winter Sale Special Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: scxmas70

CCAR-P Exam Dumps - Claude Certified Architect - Professional

Searching for workable clues to ace the Anthropic CCAR-P Exam? You’re on the right place! ExamCert has realistic, trusted and authentic exam prep tools to help you achieve your desired credential. ExamCert’s CCAR-P PDF Study Guide, Testing Engine and Exam Dumps follow a reliable exam preparation strategy, providing you the most relevant and updated study material that is crafted in an easy to learn format of questions and answers. ExamCert’s study tools aim at simplifying all complex and confusing concepts of the exam and introduce you to the real exam scenario and practice it with the help of its testing engine and real exam dumps

Go to page:
Question # 25

A Claude-based research assistant begins producing responses that confidently contradict its retrieved source documents despite no change to the retrieval pipeline.

Which two diagnostic actions most directly identify the root cause of this behavior? (Select two.)

A.

Increase the context-window size to allow more retrieved chunks per query.

B.

Switch the retrieval index to a denser embedding model to improve chunk-relevance scores.

C.

Determine whether the failure reproduces on the previous model version to test for a model mismatch.

D.

Reduce the temperature setting to lower response variance across all query types.

E.

Inspect the system-prompt grounding instructions to determine whether citation constraints remain intact.

Full Access
Question # 26

You must present an architectural recommendation to deploy a Claude-based contract review assistant to a steering committee that includes the CFO, the general counsel, and the CIO. Each stakeholder cares about different aspects of the decision.

How should you structure the recommendation document?

A.

Lead with the technical architecture diagram and the full component list before any other section.

B.

Lead with detailed cost projections across the full multi-year horizon before the rationale section.

C.

Present the same dense narrative throughout with no stakeholder differentiation in any section.

D.

Lead with the architectural decision, then address each stakeholder’s primary concerns directly.

Full Access
Question # 27

You are integrating Claude Code into the team’s pull-request workflow. The team wants AI-assisted review without removing human approval.

Which integration design best fits this requirement?

A.

Claude Code reviews the pull request and posts a structured analysis as a comment, while a human reviewer retains the approval decision under the existing branch-protection rules.

B.

Claude Code merges every pull request automatically after completing its analysis, bypassing human approval and the existing branch-protection rules.

C.

Claude Code disables all existing branch-protection rules to streamline the merge process, removing human approval as a required gate.

D.

Claude Code silently deletes pull requests it assesses as low quality without posting a comment or notifying the author.

Full Access
Question # 28

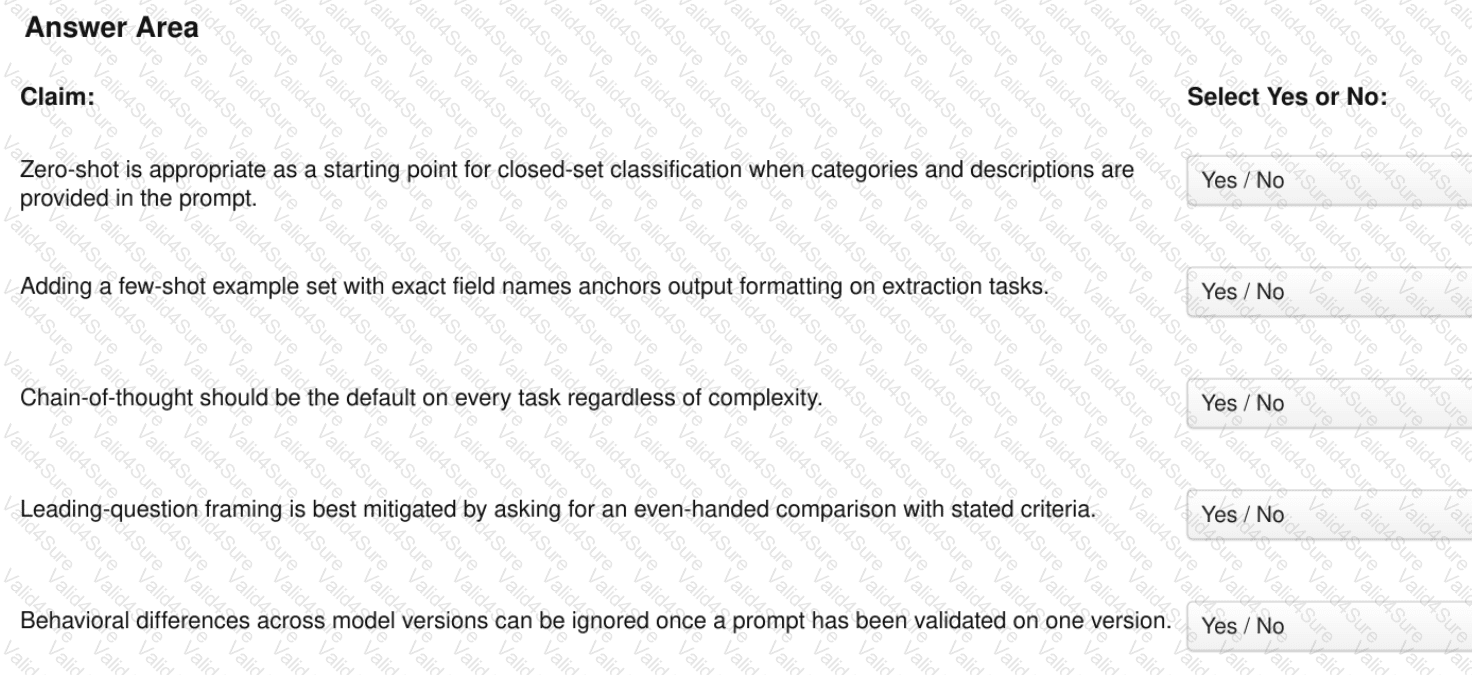
You are evaluating prompting claims in a peer’s design document.

For each claim, select yes if the claim reflects sound practice. Otherwise, select no.
Full Access
Question # 29

You are reviewing a customer-support agent’s configuration. Each candidate tool falls into one of four categories: (1) required to complete defined tasks, (2) frequently used and reduces hand-offs, (3) occasionally useful for unrelated work, (4) speculative future utility.

Which categories should typically remain in the agent configuration?

A.

Only category 3, because occasionally useful tools for unrelated work provide broader coverage and should take priority over tools required for the agent’s defined tasks.

B.

Only category 4, because speculative future-utility tools provide the most flexibility and should be configured even when no defined task currently requires them.

C.

Categories 1 and 2 only, because they map to defined tasks and the agent’s regular hand-offs.

D.

All four categories, because broader tool access is categorically better for agent performance regardless of whether the tools map to defined tasks or regular hand-offs.

Full Access
Question # 30

You are comparing two configurations for an internal compliance Q & A assistant. Configuration X reduces top-k retrieval and uses a lighter model, lowering p95 latency by 38 percent while producing a measured 2 percent reduction in the accuracy benchmark. Configuration Y retains the existing top-k retrieval setting and heavier model, with unchanged p95 latency and no measurable change in accuracy. The deployment’s stated priorities are accuracy first and latency second.

Which configuration is the better recommendation?

A.

Configuration X, because the 2 percent accuracy reduction falls within normal benchmark variance and is not a meaningful regression.

B.

Configuration Y, because the deployment’s stated priority is accuracy first, and Configuration X produces a measured reduction in accuracy.

C.

Configuration X, because lower latency generally matters more than accuracy, regardless of the deployment’s stated priorities.

D.

Configuration X, because a 38 percent latency improvement outweighs a 2 percent accuracy reduction as a general rule across compliance deployments.

Full Access
Question # 31

A loan pre-qualification assistant shows 94 percent approval recommendations that match the human underwriter decision. The fairness team has reviewed approval rate parity across protected groups and reported no significant difference. A board member has asked whether this evidence is sufficient to declare the assistant fair.

Which two Discernment-competency findings should you report? (Select two.)

Each correct answer presents part of the solution.

A.

Approval rate parity does not by itself assess error rate parity across protected groups.

B.

Match with human underwriters does not establish freedom from underwriter-introduced bias.

C.

The 94 percent match rate is sufficient evidence of fairness for the assistant’s decisions.

D.

The fairness team’s review process likely missed at least some of the protected groups studied.

E.

A larger sample is needed before any meaningful fairness claim can be made about the model.

Full Access
Question # 32

The platform team at Trenova Systems, Inc. needs to reduce per-query cost and p95 latency for a high-volume Claude pipeline without degrading output quality on the core use case.

Which two optimizations directly target both cost and latency simultaneously? (Select two.)

A.

Enable prompt caching on the static system-prompt prefix to reduce billable input tokens on repeated calls.

B.

Route straightforward query types to a smaller, faster Claude model and reserve the full model for complex cases.

C.

Increase max_tokens to reduce the frequency of truncated responses requiring follow-up calls.

D.

Add a retrieval step that fetches the full source corpus into the context window before generation.

E.

Expand the system prompt to include additional few-shot examples on every request.

Full Access
Go to page: