Databricks-Generative-AI-Engineer-Associate Exam Dumps - Databricks Certified Generative AI Engineer Associate
Searching for workable clues to ace the Databricks Databricks-Generative-AI-Engineer-Associate Exam? You’re on the right place! ExamCert has realistic, trusted and authentic exam prep tools to help you achieve your desired credential. ExamCert’s Databricks-Generative-AI-Engineer-Associate PDF Study Guide, Testing Engine and Exam Dumps follow a reliable exam preparation strategy, providing you the most relevant and updated study material that is crafted in an easy to learn format of questions and answers. ExamCert’s study tools aim at simplifying all complex and confusing concepts of the exam and introduce you to the real exam scenario and practice it with the help of its testing engine and real exam dumps
A Generative AI Engineer I using the code below to test setting up a vector store:
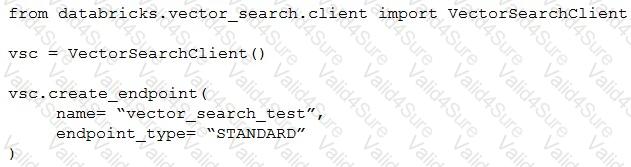
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
A Generative AI Engineer needs to allocate costs for an agent deployed via Agent Framework behind AI Gateway. The finance team requires daily reporting by workspace and endpoint, including token usage and request counts. The engineer wants to query this data with SQL and join it to an internal cost-center mapping table.
Which table type best serves their needs?
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
A Generative Al Engineer is creating an LLM system that will retrieve news articles from the year 1918 and related to a user ' s query and summarize them. The engineer has noticed that the summaries are generated well but often also include an explanation of how the summary was generated, which is undesirable.
Which change could the Generative Al Engineer perform to mitigate this issue?
A Generative AI Engineer has deployed a customer-support agent in production that retrieves product documentation and generates responses. SMEs have been reviewing agent responses and providing feedback through a web interface that captures ratings of 1–5 stars and written comments. The engineer needs to systematically collect this feedback and use it to create an evaluation dataset that can be used to compare future agent versions against the current baseline performance.
Which approach should the engineer use to accomplish this task?